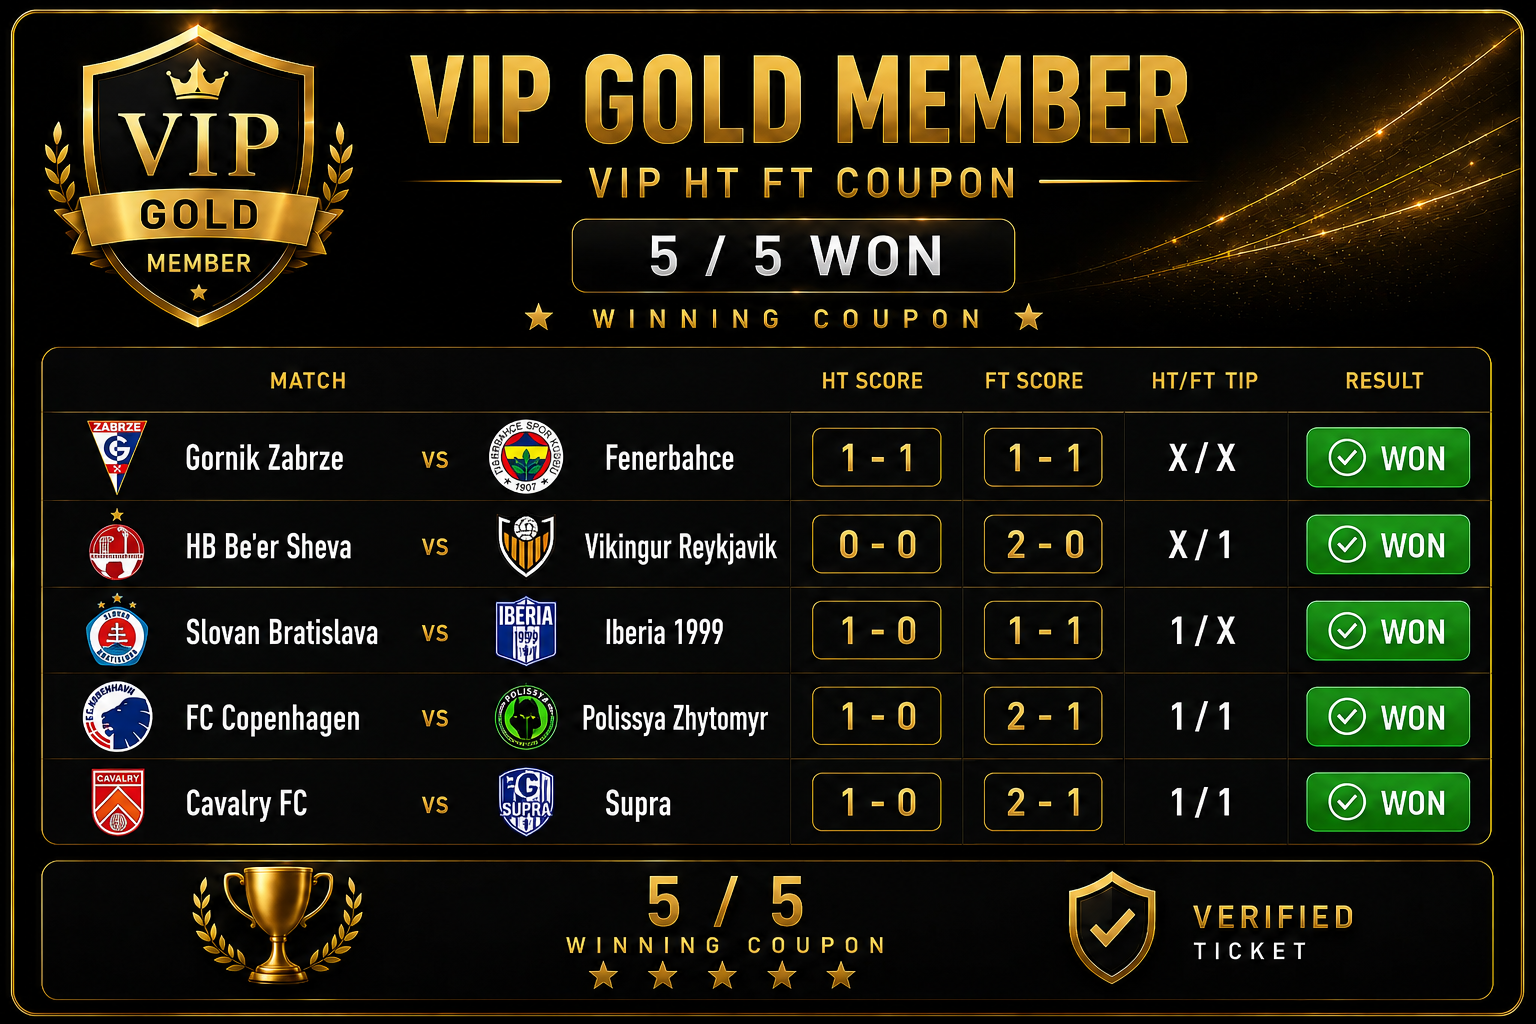
A football betting claim can sound persuasive while saying remarkably little. A team may be described as “certain to score”, a method may advertise an 80% strike rate, or a tipster may present a run of winning screenshots. None of those statements can be assessed properly until we know exactly what was predicted, at what odds, over which sample and under which recording rules.
The correct response is not reflexive disbelief. It is disciplined separation. What is the claim? What evidence directly supports it? Which hidden assumptions connect the two? What ordinary counter-case could produce the same result? Only after those questions are answered should confidence enter the discussion. A good audit will not turn uncertainty into certainty. It will show whether the confidence being requested is proportionate to the evidence supplied.
First, convert the promotion into a testable claim
Promotional language often combines several different claims. “This system regularly finds safe home wins” may contain a frequency claim, a risk claim, a selection-method claim and an implied profitability claim. Those are not interchangeable.
Rewrite the statement in terms that could be proved wrong. Identify the market, competition scope, publication time, quoted odds, staking rule, settlement rule and evaluation period. If “regularly” has no numerical meaning, ask what rate is intended. If “safe” is used, ask whether it refers to strike rate, drawdown, price range or merely the writer’s confidence. If “profitable” is claimed, ask whether that means gross winners, net profit, yield or something else.
Classification matters because different claims require different evidence. A factual claim, such as a club having won its previous five matches, can be checked against records. A predictive claim estimates what will happen next. A value claim says the available odds exceed the fair price. A performance claim says a method has succeeded historically. Historical form may contribute to a forecast, but it does not by itself establish value at the available price.
If a claim cannot be stated clearly enough to fail, it cannot earn strong confidence. Vagueness is not evidence of deception, but it does protect a claim from meaningful examination.
Ask whether the evidence answers the claim actually made
Evidence can be genuine yet irrelevant. A list of recent wins may show that a team has performed well; it does not establish that the next-match odds are generous. A model description may sound sophisticated; it does not demonstrate that selections were published before kick-off. Screenshots may show settled winners; they do not reveal deleted losses.
Start with provenance. Where did the figures come from? Can the underlying record be inspected? Were predictions timestamped before events? Were the quoted odds available when followers could act? Have postponed, abandoned and void bets been treated consistently? A claim about long-term performance needs a complete ledger, not a curated gallery.
Then test relevance. A both-teams-to-score record cannot validate a correct-score claim merely because both concern goals. Results from one league, price band, season or market type may not transfer to another. A system built around short-priced home favourites should not be credited with proving an edge in away-win or high-odds correct-score markets. Back-tested performance is evidence about the historical test conditions, not automatic evidence about future deployment.
Finally, separate observation from interpretation. “Four of the last five matches went over 2.5 goals” is an observation, assuming the record is correct. “Therefore the next match is likely to go over” is an inference. “Therefore over 2.5 goals is a good bet at the current odds” is a further inference. Each step needs its own defence.
| Claim | Evidence that directly bears on it | What does not establish it |
|---|---|---|
| The next selection is likely to win | A defined probability estimate supported by relevant inputs and calibration evidence | Recent team form alone |
| The offered odds represent value | Estimated fair probability compared with an obtainable price | A high predicted win probability without reference to odds |
| The method has been profitable | Complete timestamped selections, stakes, prices and net returns | Winning screenshots or strike rate alone |
| The process is repeatable | Rules fixed before testing and performance on new data | A rule reconstructed from its best historical period |
The denominator and recording rules matter more than the headline
A strike rate without its denominator is almost content-free. Fourteen winners from 20 bets and 350 winners from 500 bets both produce a 70% strike rate, but they do not provide the same degree of evidence. The smaller record is more exposed to ordinary variation.
Even a large total can exaggerate certainty when observations are correlated. Several bets derived from the same match, model signal or league condition are not equivalent to independent tests. A tipster who backs home win, home team over 1.5 goals and half-time/full-time on the same fixture may record three selections, but the underlying judgment is substantially one match-level view. Nor should a record built across shifting methods be treated as one stable sample.
Check what entered the denominator. Were all tips recorded, including late additions? Were free tips and paid tips combined selectively? Were pushes, voids and abandoned matches handled according to a stated rule? Were losing periods omitted because they belonged to an earlier version of the method? If the selection rule changed after losses, the advertised total may describe a sequence of experiments rather than a repeatable process.
There is no universal sample size that proves reliability. More observations generally reduce sampling uncertainty, but quantity does not repair biased selection, inconsistent recording or a method reconstructed after seeing the results.
Recalculate performance through the odds, not the win count
Winning often is not the same as betting profitably. A strategy can produce many correct selections and still lose if its prices are too short. Conversely, a lower strike rate can be profitable when winners are obtained at sufficiently large odds.
With decimal odds, the reciprocal gives the break-even probability before allowing for the bookmaker’s margin. Odds of 2.00 correspond to a 50% break-even rate. In an explicitly illustrative example, an estimated 60% chance at obtainable odds of 2.00 implies an expected return of 0.20 units per 1 unit staked: 0.60 multiplied by 2.00, minus 1. That is a value argument only if the 60% estimate is well calibrated. An unsupported probability estimate cannot be made persuasive merely by putting it into a formula.
For a historical record, request stakes, odds and net returns for every selection. Yield should be calculated as net profit divided by total amount staked. Average odds alone are insufficient because returns depend on which individual prices won and lost. Variable staking requires additional scrutiny: a profitable headline can be driven by one unusually large winning stake rather than consistent forecasting.
Quoted prices must also be realistic. Best-in-market odds recorded briefly, after publication or at negligible limits may not represent the experience available to a typical reader. Closing-price comparison can provide useful supporting evidence about price quality, but it is not proof of future profit and does not replace settled results.
Search for the choices made after the results were known
Many impressive records are not fabricated. They are selected. A method may be tested across numerous leagues, time windows, indicators, odds bands and thresholds, with only the strongest combination reported. The final result then reflects both any genuine signal and the advantage of searching through alternatives.
Ask when the rule was fixed. Was the strategy specified before the test period, or assembled after observing which variables worked? Were unsuccessful variants disclosed? Is there an untouched out-of-sample period? A rule that performs well only in the data used to design it may have captured noise rather than a durable relationship.
Hindsight can enter through less obvious routes: excluding inconvenient matches, redefining a qualifying bet, switching odds sources, treating a late team-news change as an exception or presenting only the strongest month. Each decision may have a defensible explanation in isolation. The problem is cumulative discretion. The more choices made after outcomes are visible, the less the headline result can be treated as an independent test.
The counter-case should be stated fairly. A revised method is not automatically invalid, and football markets, squads and competition conditions do change. But a materially revised method needs fresh evaluation. Old performance cannot simply be inherited by a different process.
Audit the source as well as the numbers
A source should be judged by what can be checked, not by confidence of presentation. Useful signs include pre-match timestamps, an unedited archive, explicit odds, stable settlement rules, visible losing periods and prompt correction of errors. None proves predictive skill, but each reduces the opportunity to rewrite the record.
Incentives matter. A source rewarded for subscriptions, attention or rapid turnover may benefit from dramatic certainty even when the evidence supports only a narrow probability edge. That conflict does not prove a claim false. It changes the burden of verification.
Watch for asymmetrical explanations. If winners are credited to the method while losses are blamed on referees, bad luck or unexpected team selection, the process has been protected from failure. Football contains randomness, including red cards, injuries and late tactical changes, but randomness cannot be invoked only when results disappoint.
Secrecy needs careful treatment. A model owner may reasonably protect proprietary details. Full code is not required to assess every performance claim. However, confidentiality is not a substitute for a verifiable record. The source can withhold the recipe while still documenting what was predicted, when it was published, the available price and how it was settled.
End with a proportionate verdict, not a binary label
An audit does not have to conclude that a claim is either proven or fraudulent. More useful verdicts distinguish what survives scrutiny from what remains uncertain.
A claim may be unsupported because necessary evidence is absent. It may be plausible but unverified because the reasoning makes sense while the performance record cannot be checked. It may be historically supported when a complete record matches the stated method, although future transfer remains uncertain. It should be called contradicted only when reliable evidence conflicts with a material part of the claim.
Confidence should fall when small samples, correlated bets, inaccessible odds or discretionary exclusions are present. It can rise when the claim was specified in advance, selections were timestamped, all outcomes were retained and similar performance appeared in genuinely new data. No single feature settles the matter.
The final question is practical: what decision would change if the claim were true, and what is the cost if it is wrong? Where evidence is incomplete and downside is material, the defensible response is often to decline the bet rather than invent precision. Passing is an audit outcome, not an analytical failure.
| Audit question | Stronger practice | Reason for caution |
|---|---|---|
| Were selections visible before kick-off? | Permanent timestamped publication | Undated or editable posts |
| Can every result be found? | Continuous ledger containing wins, losses and voids | Isolated screenshots or monthly highlights |
| Were the odds usable? | Named source, publication time and realistic availability | Best price recorded retrospectively |
| Are errors handled consistently? | Public corrections and fixed settlement rules | Explanations that change according to the outcome |
Trust should be earned at the level of the claim
The purpose of an audit is not to demand impossible certainty. It is to prevent a modest observation from being promoted into a confident betting conclusion without the intervening evidence. Define the claim, inspect the record, price the prediction, expose discretionary choices and state the remaining uncertainty plainly.
What survives may still be useful. It will usually be narrower than the original promotion: evidence of a promising process rather than proof of profit, or a plausible forecast rather than a “sure” outcome. That reduction is not excessive scepticism. It is the point of scrutiny.